ML evaluation
labelbudget
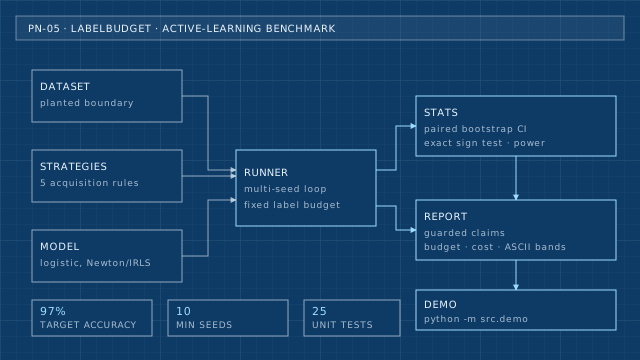
An active-learning benchmark that reports labels needed to reach a target accuracy, with variance across many seeds, next to a prominent random-sampling baseline. A comparison guard refuses claims the evidence does not support.
Drawing
Highlights
- Target accuracy is 97% of the full-pool score; the random baseline is always run.
- Paired bootstrap CI and exact sign test, with no comparative claim below 10 seeds.
- Pure Python standard library with 25 tests.